How to give individual grades for group work, fairly and defensibly

Every teaching team that assesses group projects eventually receives the same email from a student who did most of the work and wants to know why everyone got the same mark. The instructor usually agrees that it is unfair and usually has no evidence with which to do anything about it.
This article sets out a method for producing individual grades from a shared piece of work. None of it is complicated, but each step contains a choice, and those choices are what make the final grade either easy to explain or easy to contest.

Start by separating two different things
A group project produces two things worth assessing, and confusing them causes most of the trouble later on.
The first is the product: the report, the design, the presentation, the code. This is a collective achievement and it gets one mark, given by the instructor against the normal criteria.
The second is the process: how each person contributed to producing it. This is individual, and it is the only part where peer input has any authority, because teammates are the only people who observed it.
Once you hold these apart, the design question becomes clear. You are not asking students to grade each other's work. You are asking them to report on a process that only they can see, and then using that report to adjust a mark that you gave.
Choose how the adjustment works
There are three common approaches, and they suit different courses.
Weighting factor. Each student receives a contribution factor derived from peer ratings, usually centred on one. The group grade is multiplied by the factor. A group grade of seventy with factors of 1.05, 1.0, 1.0 and 0.8 produces individual grades of roughly 73, 70, 70 and 56. This is the most common method, it is transparent, and it is the easiest to explain.
Capped adjustment. The same idea, but you set limits, for example that no individual grade can move more than ten points from the group grade unless the instructor reviews the case. This protects against a group that decides collectively to punish one member, and it is worth having in any course where the grade carries progression consequences.
Threshold with instructor review. Everyone receives the group grade unless the peer data flags a case, at which point the instructor investigates and makes a judgement. This produces fewer disputes and is less work in courses where free riding is rare, but it does nothing to reward strong contributors, which students notice.
For most undergraduate courses a weighting factor with a cap is the right starting point. Whichever you choose, write it into the assignment description before the project starts, with a worked numerical example. Students accept an algorithm they were shown in week one far more readily than one they learn about with their grade. If you want to know more about how the calculation works and what students see, our Group Member Evaluation FAQ explains it step by step.
Ask about behaviour, not about people
The quality of the whole system depends on the criteria students rate each other against, and this is where most implementations go wrong. Asking students to rate "overall contribution" out of ten produces a popularity measurement with a grade attached to it.
Useful criteria describe observable behaviour during the project. Did this person complete their agreed tasks by the agreed deadline. Did they attend the meetings the group scheduled. Did they respond to messages within a reasonable time. Did they give useful input on other people's sections rather than only their own. Did they help the group make decisions when it was stuck.
Each of those is something a teammate genuinely witnessed, and each can be answered without making a judgement about whether someone is clever or likeable. Use a short scale with described points rather than numbers alone, because "completed all tasks on time" and "needed several reminders" mean the same thing to everyone, whereas a four out of five does not.
Require a brief comment alongside any rating at the bottom or top of the scale. This single requirement does more for data quality than anything else, because it forces a student to hold a specific memory in mind before penalising a teammate, and it gives you evidence if the grade is later challenged.
Include self evaluation, and use the gap
Ask every student to rate their own contribution against the same criteria before they see anyone else's ratings. Two things come out of this.
The first is metacognitive. Students are made to think about their own behaviour in the team, which for some of them is the first time anyone has asked. The second is diagnostic. The gap between a student's self rating and the ratings their teammates gave them is one of the most informative numbers in the whole exercise.
A student who rated themselves highly and was rated poorly by everyone else is usually not a cynical free rider. More often they genuinely did not realise, because they attended the meetings and felt present while doing very little of the work. A student who rated themselves poorly and was rated well by everyone is often an anxious high performer who needs to hear that. Both cases are worth a short conversation, and neither is visible without the self rating. Analytics that surface these discrepancies automatically, as in Group Member Evaluation, turn this from a spreadsheet exercise into a two minute scan.
Run it more than once
A single evaluation at the end of a project tells you what went wrong after it is too late to fix. Two evaluations, one at the midpoint and one at the end, change the activity completely.
The midpoint round is formative. It carries no grade weight, the results go to the students, and its purpose is to let a team correct itself while there is still time. This is where most of the value sits, because a quiet member who gets an early signal that their teammates have noticed usually adjusts.
The end round is summative and feeds the grade adjustment. Telling students in advance that there will be a midpoint round also changes behaviour from week one, because contribution stops being something that can be caught up on the night before submission.
Handle anonymity carefully
Anonymous peer evaluation produces more honest ratings, which is why most courses use it. It also creates the situation where a student receives a low mark and cannot see who said what, which feels arbitrary.
The workable compromise is anonymity between students combined with full visibility for the instructor. Students do not see who rated them, so honesty is protected, and the teaching team sees everything, so a pattern of malicious rating can be identified and a challenged grade can be explained. Tell students explicitly that this is the arrangement, because "your ratings are anonymous to your teammates but visible to me" is a sentence that improves the quality of what they write.
In small groups, particularly groups of three, anonymity is partly theoretical, because students can often work out who said what. This is another reason to require comments to be about behaviour rather than about people.
Explain the result before anyone asks
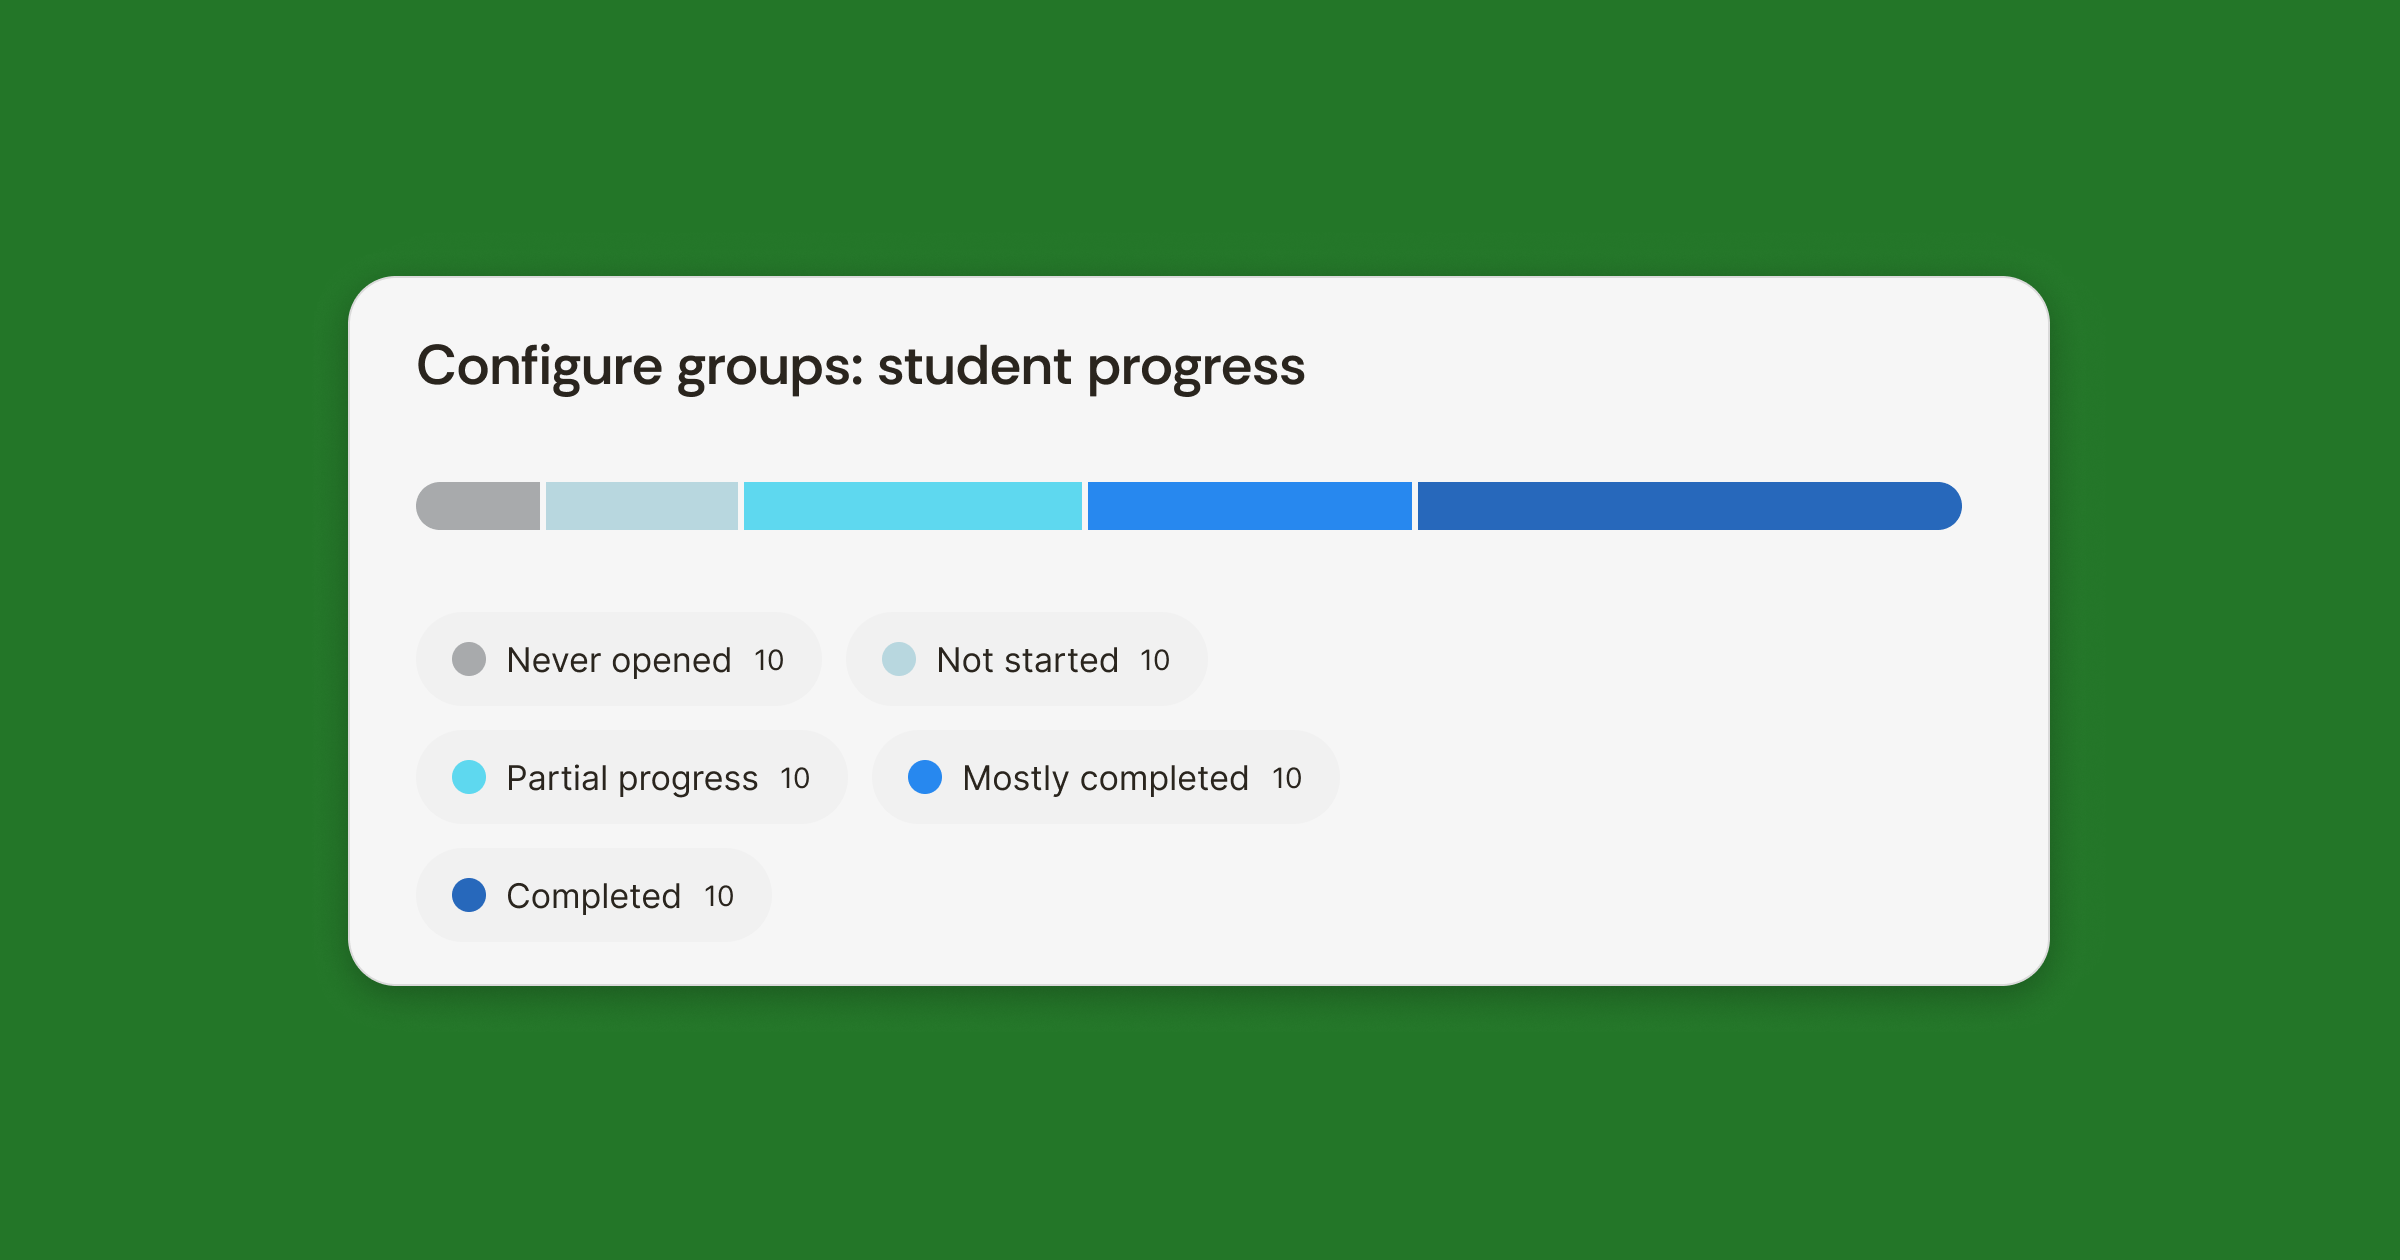
The last step is the one that prevents appeals. When individual grades are released, each student should be able to see the group grade, their own contribution factor, how the factor was calculated, and the anonymised comments about their contribution.
This turns a contested grade into an explained one. The student who lost points can see that four teammates independently reported the same thing. The student who gained points can see why. And the teaching team has a record that was generated by a stated process rather than by a judgement call made under time pressure.
What this is really for
It is tempting to frame all of this as a way of catching free riders, and that is certainly part of it. The more interesting effect is upstream. When students know from the first week that contribution is visible, measured against named behaviours, and reported by teammates at the midpoint as well as at the end, the group dynamics change before any grade is calculated.
That is the real return on setting this up properly. Fewer difficult emails at the end of the semester, because fewer teams reached the end of the semester in trouble.
Where to go next
If you would like to see how this works inside the tool itself, the Group Member Evaluation solution page shows how criteria, weighting, self evaluation and outlier detection are configured in one activity. The Group Member Evaluation FAQ is a good next stop if you have the practical questions that usually come up before a first run, such as how the activity sits in your LMS, what students see, and what happens when someone misses a deadline.
It is also worth looking at the tools that sit naturally alongside this one, including Group Formation, Team Based Learning and Peer Review. You can see how they all fit together on the FeedbackFruits tool suite page, or read more about what a feedback and assessment solution actually is if you are building the case for your institution.
And if you want to keep reading on this topic, we have Eliminating free riding in group work, Group member evaluation criteria, with examples and 5 ways to stimulate collaboration with Team Based Learning.